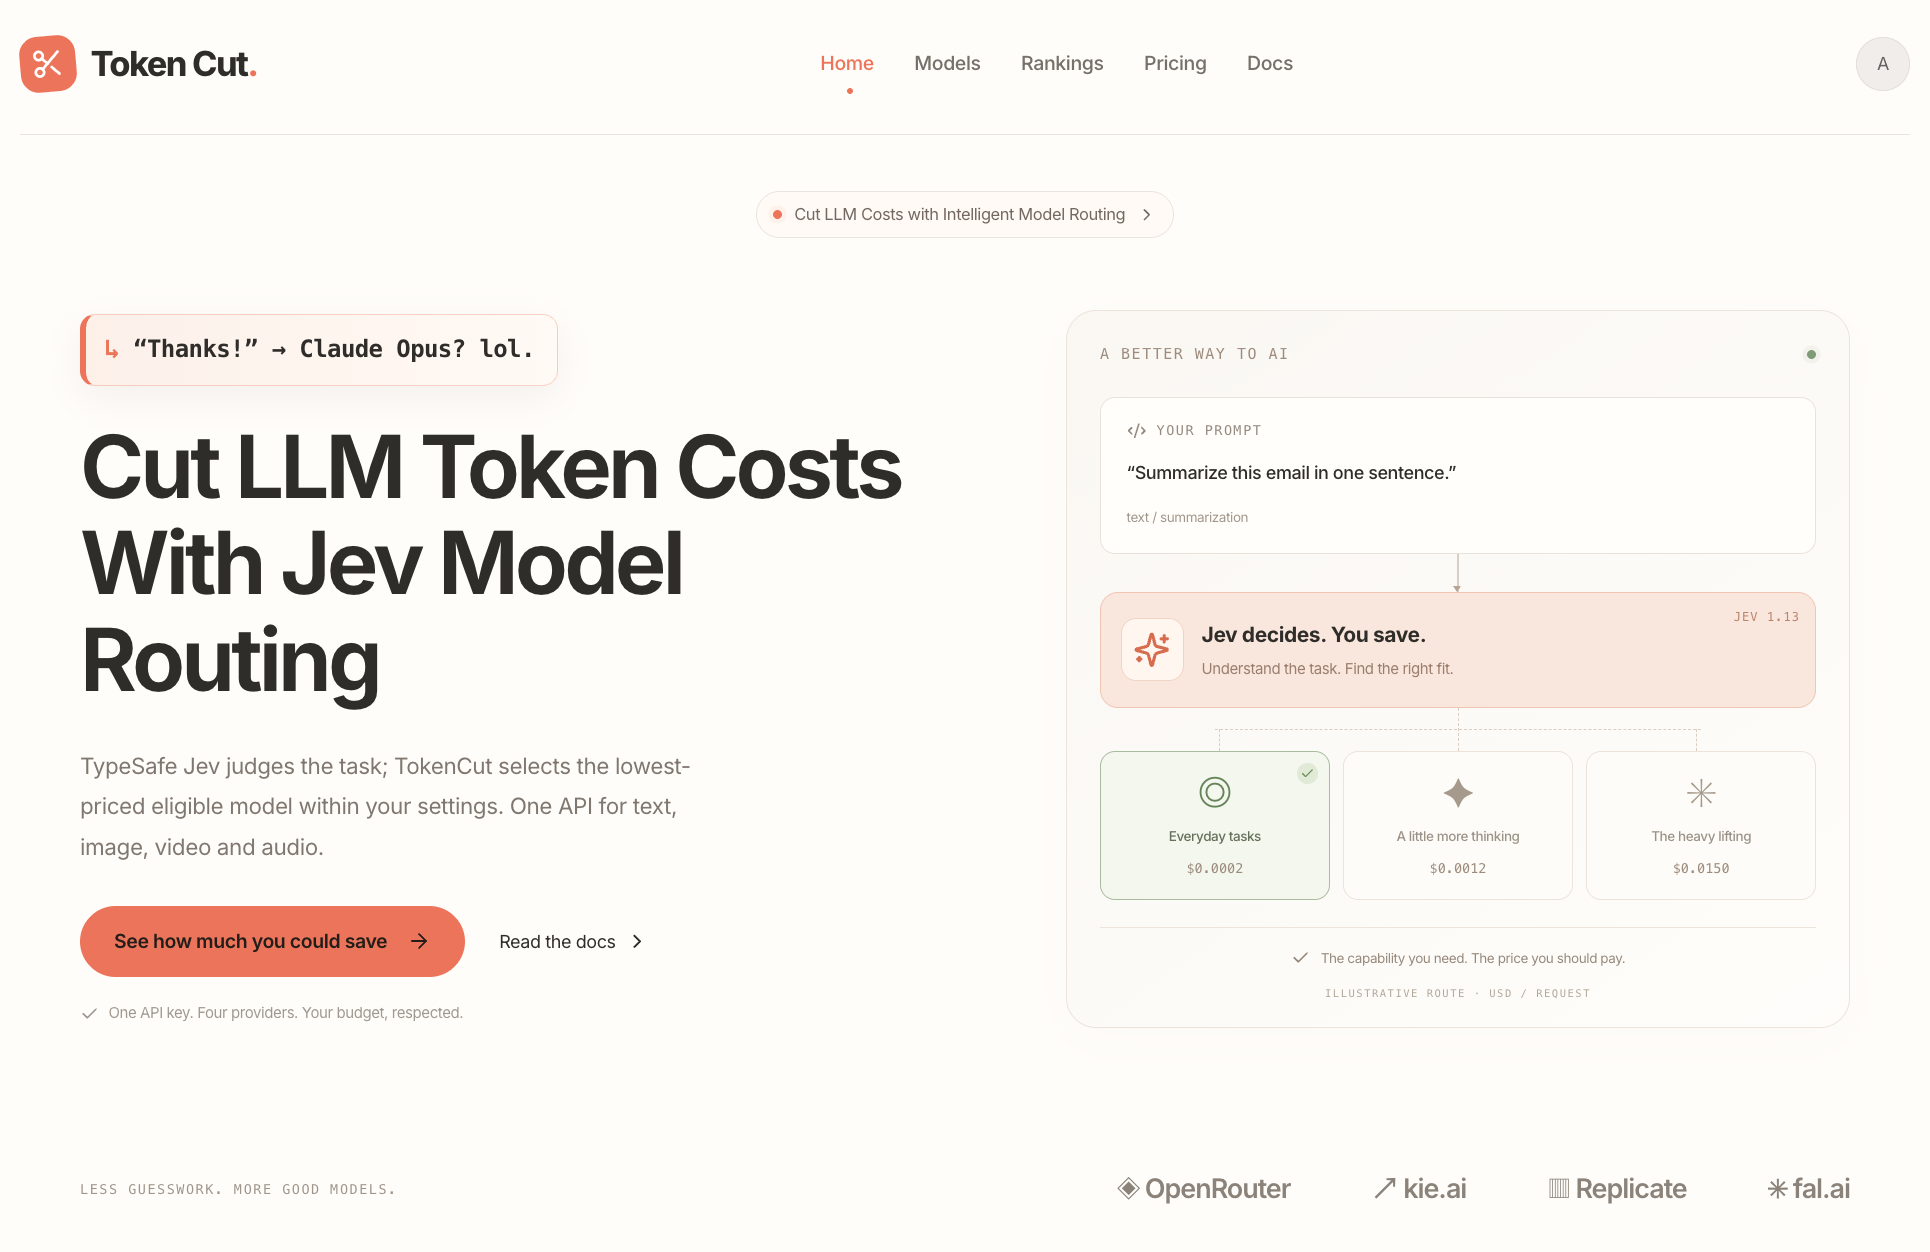
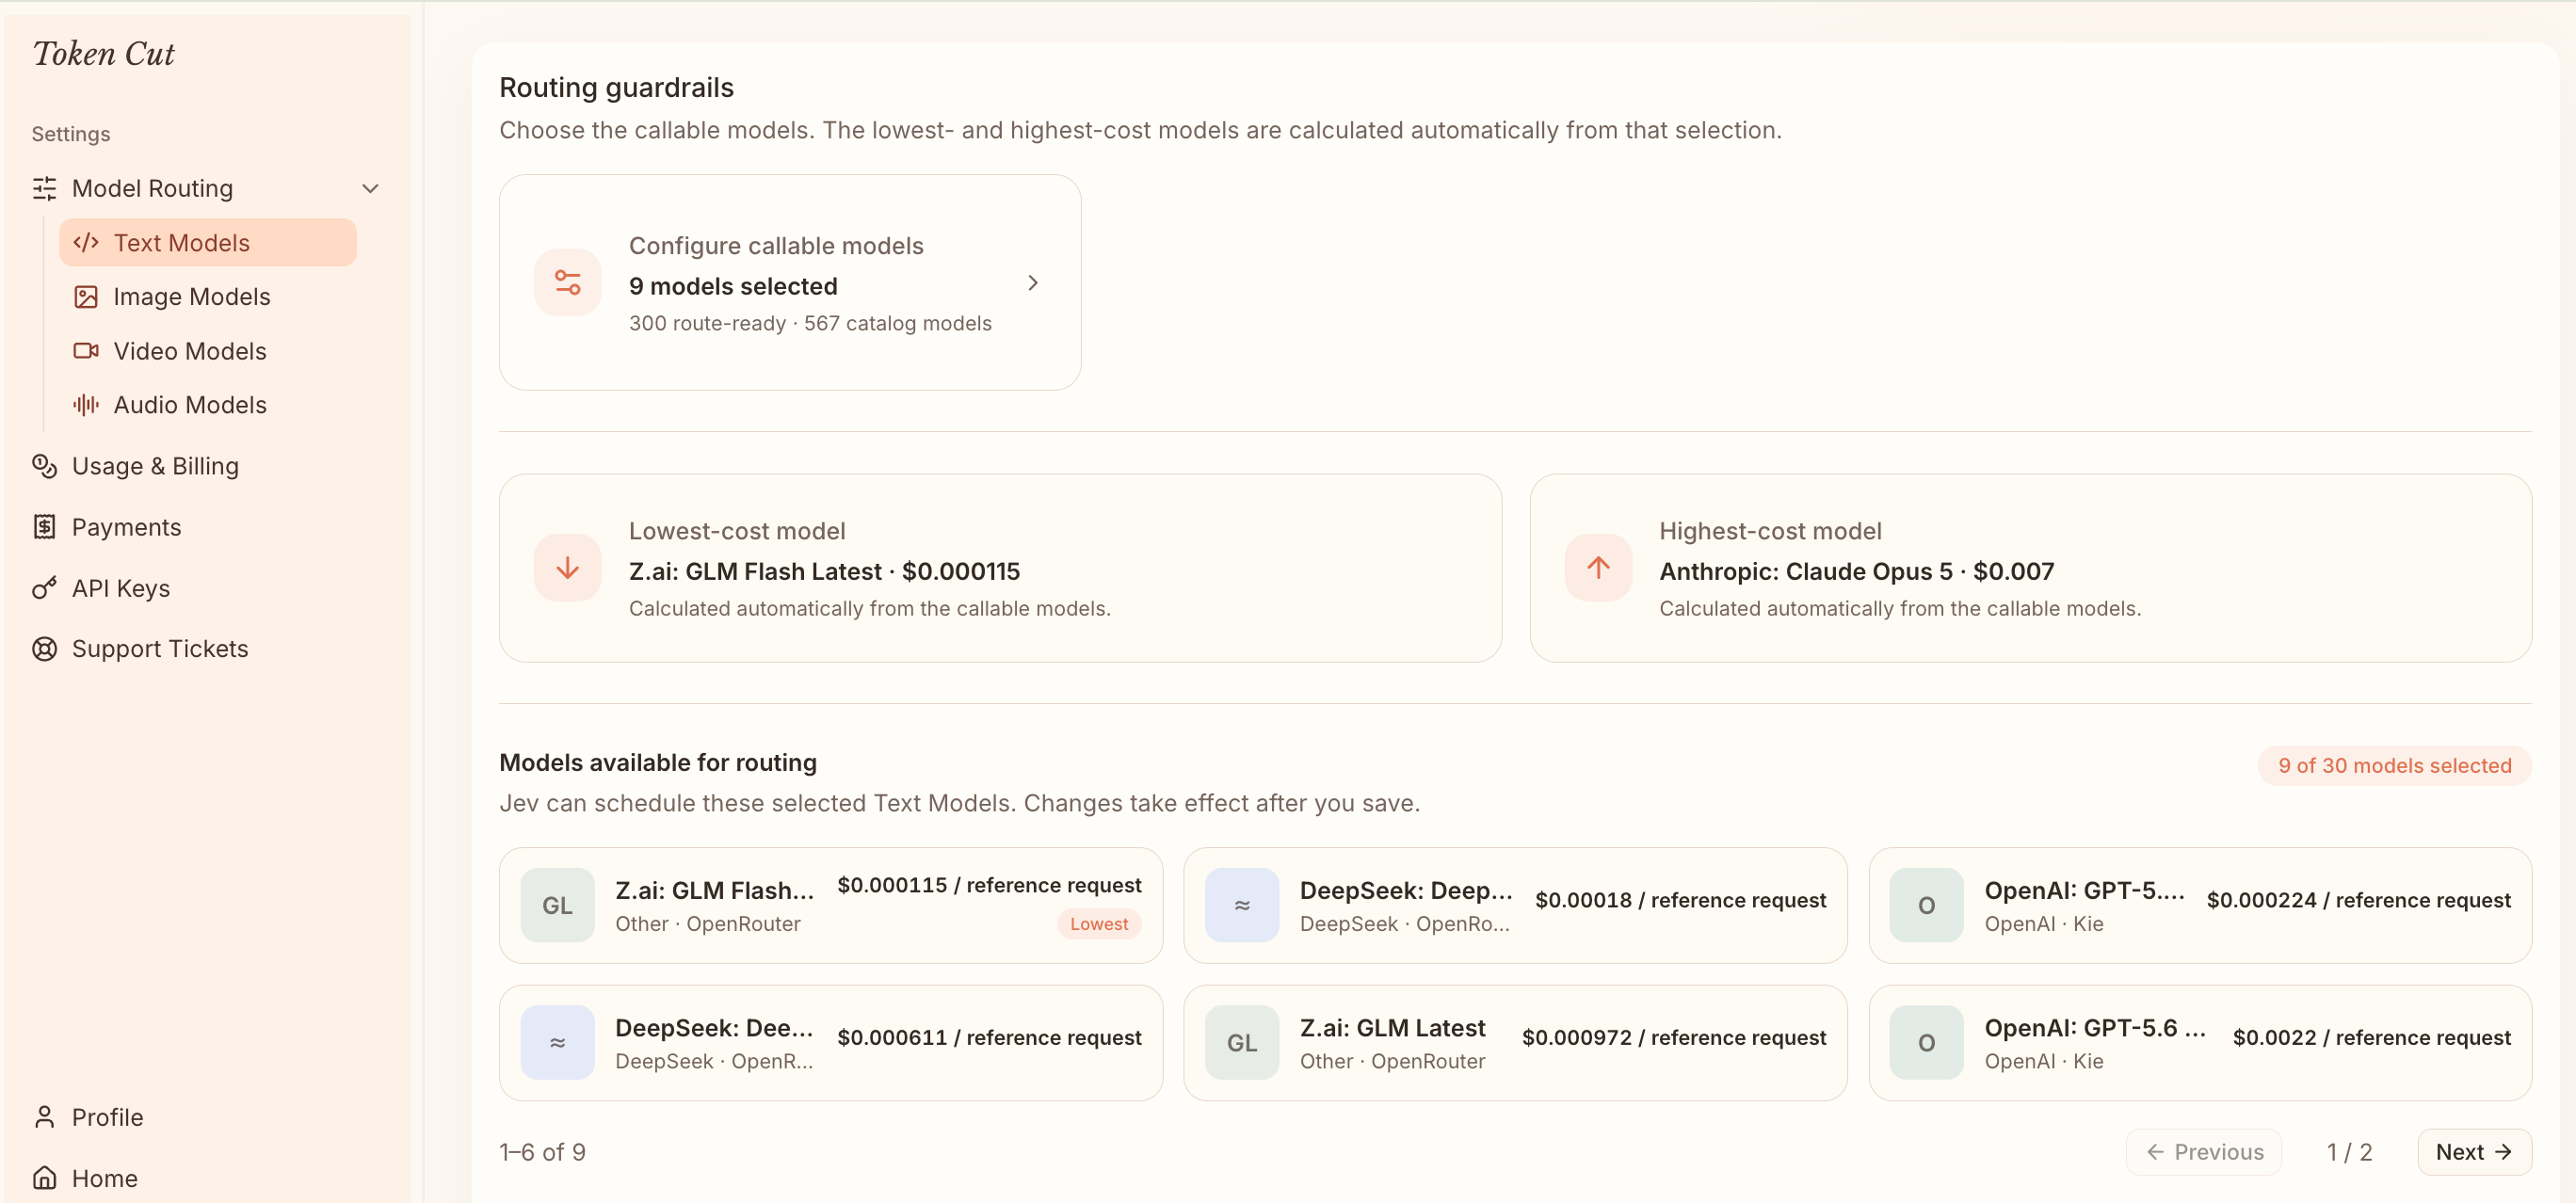
Token Cut uses Jev model routing to minimize LLM token costs by routing prompts to the cheapest model that can handle them. It reduces token costs and latency while you wire a solution in minutes.
Key benefits include:
- Reduces token costs for LLMs by routing to cost-effective models
- Utilizes advanced routing algorithms to optimize model selection
- Improves model efficiency and latency for prompts
- Compatible with various LLM architectures
Perfect for developers using LLMs who want to cut costs and latency while maintaining performance.